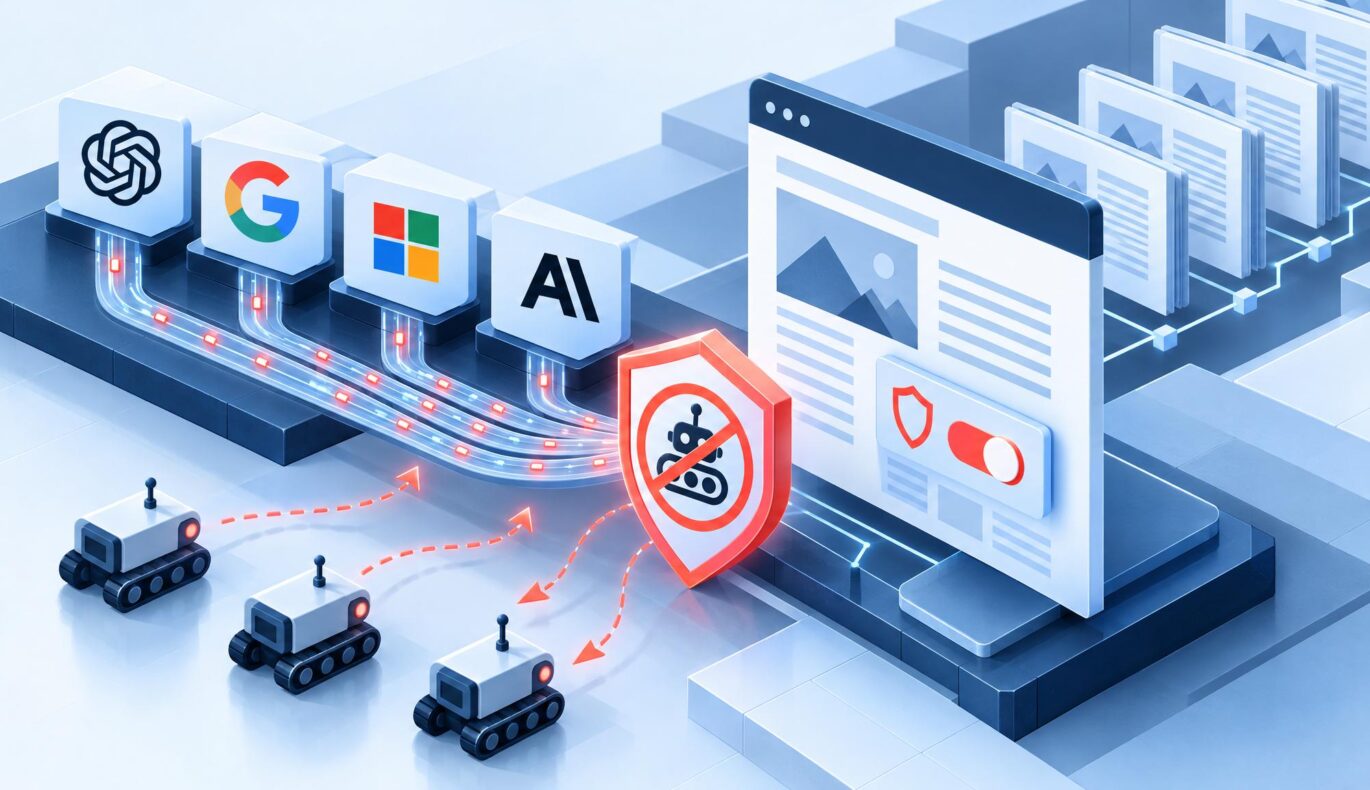
OpenAI, Google, Microsoft, and Anthropic say they will adopt a shared standard intended to let publishers opt out of AI scraping through one website-level setting. The proposal affects website owners, developers of crawlers, and AI companies: instead of configuring preferences separately for each provider, a publisher could publish a common signal in its robots.txt file.
What the proposed AI scraping opt-out does
The signal is described as a shared “policy token,” proposed by Kevin Kelley, a technical lead for standards at Anthropic, within the Internet Engineering Task Force (IETF). It would sit alongside existing robots.txt rules, which websites use to communicate whether web crawlers may access their content for purposes such as search indexing or archiving.
According to the supplied report, the participating companies say they will adopt the new standard. The stated change is interoperability: publishers could express their AI-training preferences once for multiple AI companies, rather than maintain separate instructions for each provider.
That does not establish that the system is already available, universally supported, or legally binding. The source material does not specify a rollout date, which AI products will read the signal first, whether the token can distinguish AI training from other forms of scraping, or how compliance will be checked.
Why publishers and developers should care
For publishers, a common control could reduce the operational burden of managing crawler preferences across a changing AI market. A small business with a public documentation site, for example, might hypothetically want its pages indexed by conventional search engines while expressing a different preference about their use for AI training; the supplied material does not confirm whether the proposed token supports that exact combination.
Developers and platform teams would need to treat the signal as part of crawler governance: document the site’s policy, test the resulting robots.txt output, and monitor which crawlers respect it. The main potential advantage is a shared convention rather than a series of provider-specific settings.
What remains unresolved about the standard
The proposal’s location in robots.txt also highlights its limitation. Such files communicate a publisher’s instructions, but the source does not describe technical enforcement, penalties for ignoring them, or remedies when content has already been collected. It likewise provides no detail on whether existing training datasets or previously scraped material would be affected.
For now, publishers should not assume that adding a new token will immediately change how AI companies use their content. The practical next step is to follow the IETF proposal and provider documentation, then verify support before changing production crawler policies.
资料来源 原创报道. 本文包含独立的编辑背景和实务分析。.
更多关于人工智能的见解: 浏览我们的 最新的AI自动化与技术文章, ,或探索 即用型自动化解决方案.